AI how-to notes · 2026-09-18 · last run 2026-09-18 · 한국어 원문
Merging several PDFs in the order you want on Windows — and whether anything built in can do it
One line summary
As far as we got, nothing that ships with Windows 11 will merge several PDFs into one file. Explorer attaches no Print command at all to a PDF, and Edge counts only the tab you are currently looking at, even with three tabs open. Opening them in Word and stringing them together does work, but our 10 pages became 13 and the text and borders changed. The only thing that kept the page count and the order intact was Python (pypdf).
Who this is for
- Anyone who has to submit a scanned cover, body and appendix as one file and can't install a merging program
- Anyone reluctant to upload company material to a "merge PDF" site
- Anyone whose merge came out in the wrong order or with the wrong number of pages
Test environment
| Item | Value |
|---|---|
| OS | Windows 11 Home 25H2 (10.0.26200.9457) |
| Shell | PowerShell 7 / Git Bash |
| Edge | 153.0.4234.32 |
| Word | 16.0 (Build 16.0.20326) |
| Python | 3.12.10 |
| Python packages | pypdf 6.14.2, PyMuPDF 1.28.0 |
| Test files | 3 dummy PDFs made for the test. No company material was used |
The files we tested with
We made three PDFs with a big stamp on every page saying which file it is and which page of that file. That way the order can be counted by eye the moment they are merged.
| File | Pages | Stamped on the pages | Size |
|---|---|---|---|
| Y1_A_표지.pdf (cover) | 2 | A-1, A-2 | 63,924 bytes |
| Y1_B_본문.pdf (body) | 5 | B-1 – B-5 | 65,899 bytes |
| Y1_C_별첨.pdf (appendix) | 3 | C-1, C-2, C-3 | 64,879 bytes |
10 pages in total. That number is the yardstick for every result below.
First question — does anything built into Windows do it?
Selecting several files in Explorer and choosing Print
We dumped the command list Explorer attaches to each file type and compared PDF against the others.
PDF : 열기(O) | Notepad++로 편집 | 즐겨찾기에 추가(F) | ... | 속성(R)
PNG : 열기(O) | 바탕 화면 배경으로 설정(B) | 인쇄(P) | 오른쪽으로 회전(T) | ...
TXT : 열기(O) | 편집 | 인쇄 | ...
Those are the Korean context-menu entries — Open, Edit, Add to Favorites, Properties, Set as desktop background, Print, Rotate right. PNG and TXT have 「인쇄」 (Print); PDF does not. We did not separately check the menu that appears when several files are selected, but a command that isn't there for one file does not materialise because you selected several. On this PC the default program for PDFs is Edge (MSEdgePDF), and it registers only two commands, open and runas, so there is no print command to call. Forcing it from the command line stops in the same place.
> Start-Process -FilePath Y1_A_표지.pdf -Verb Print
오류: 이 작업을 하기 위해 지정된 파일로 아무 응용 프로그램도 연결되어 있지 않습니다.
The error says no application is associated with the specified file for this operation.
Change the default PDF program to another viewer and 「인쇄」 may well appear. But that means you installed that viewer. What happens when you select several files and print from there, we did not test.
Opening three of them as tabs in Edge and printing
We loaded all three PDFs as tabs in one Edge window and pressed Ctrl+P. The top of the print pane reads 「합계: 2 용지」 — total, 2 sheets of paper. Only the tab in front of us (A, 2 pages) was counted. Switching the printer to 「Microsoft Print to PDF」 changed nothing.
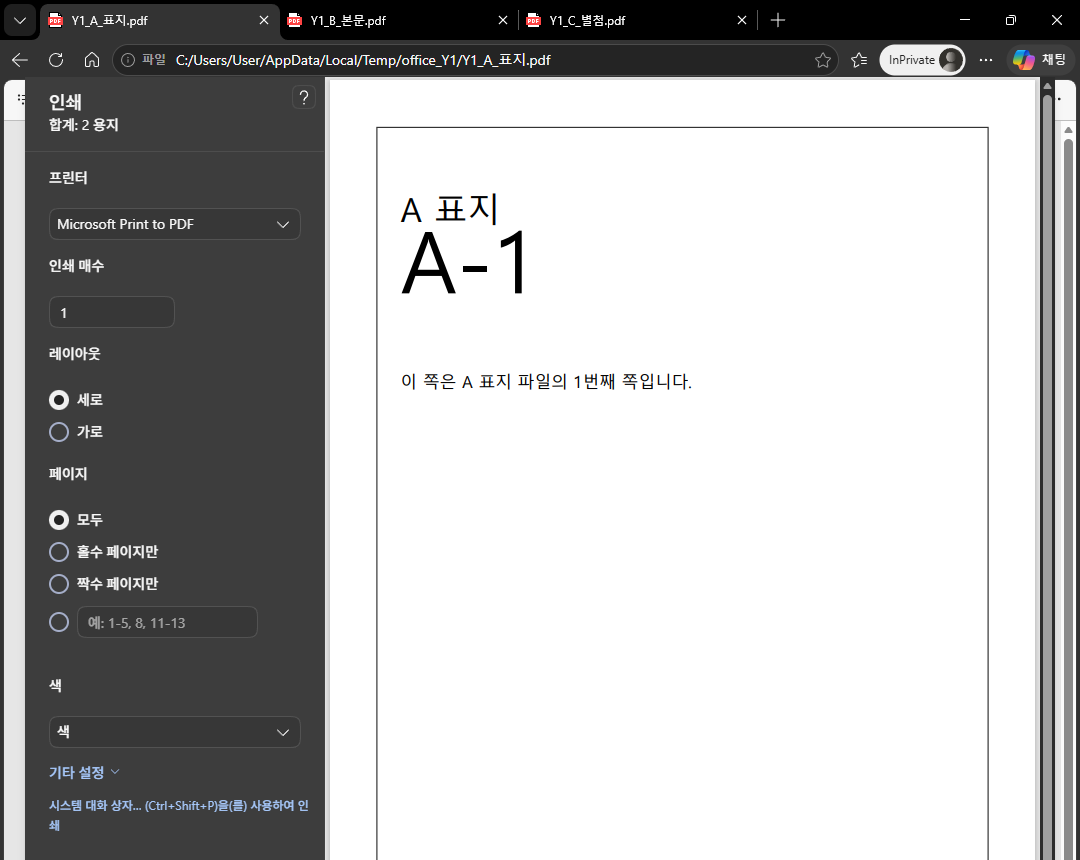
Handing them over together on the command line is blocked as well.
> msedge.exe --headless --disable-gpu --print-to-pdf=C:\...\합본.pdf --no-pdf-header-footer
    file:///C:/.../Y1_A_표지.pdf file:///C:/.../Y1_B_본문.pdf file:///C:/.../Y1_C_별첨.pdf

[0918/110125.664:ERROR:chrome\app\chrome_main.cc:321] Multiple targets are not supported in headless mode.
exit code=13   합본.pdf was never created
Pass a single file and it does finish with exit code 0 and does produce a file. That file is 1 page and 1,101 bytes, with 0 extractable characters, 0 images and 1 vector drawing. The 2 pages of the original are not in it. We did not dig into why.
Printing them one at a time through 「Microsoft Print to PDF」
With the window up, pressing Print brings up the 「다른 이름으로 프린터 출력 저장」 (Save Print Output As) dialog asking for a name, and typing a path drops one file there. We walked that procedure twice and that is what we got: printing only pages 3–5 of a 10-page document gave one file of 11,219 bytes, and printing a photo document in full gave one file of 1,641,339 bytes. One print, one file, and nowhere in the procedure is there a place to string files together.
The route that does work — opening them in Word and stringing them together
Word turns a PDF into an editable document. Insert the three PDFs one after another into a blank document, export back to PDF, and you have one file. Rather than clicking the menus, we had automation (COM) do the inserting (Selection.InsertFile) and the exporting (ExportAsFixedFormat) so we could measure the time and the page count.
InsertFile Y1_A_표지.pdf -> ok, 1.1 s, running page count = 5
InsertFile Y1_B_본문.pdf -> ok, 0.7 s, running page count = 10
InsertFile Y1_C_별첨.pdf -> ok, 0.7 s, running page count = 13
saved merged file = 62,721 bytes, 13 pages
10 pages became 13. Pages 1, 3 and 5 are blank.
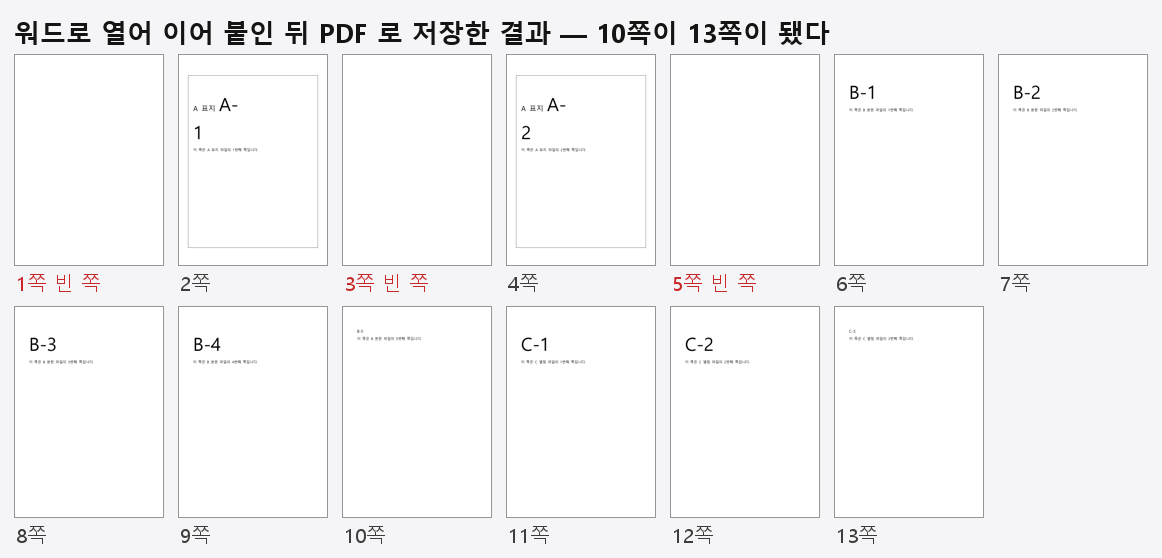
Pulling the text out page by page and comparing it with the original, this is what had changed.
| What we looked at | Original | After Word |
|---|---|---|
| Text lines on the first page | two lines, 「A 표지」 / 「A-1」 | one line 「A 표지 A-」 plus 「1」 on the next |
| Title line at the top of the B and C pages | 「B 본문」 / 「C 별첨」 present | gone |
| Vector drawings on page 1 of A | 1 | 12 on the pages holding A's content, 0 on the pages holding B's and C's |
| Largest type on the page | not measured | 72 pt on pages B-1–B-4, 16 pt on B-5 and C-3 only |
If counting pages matters, or if anything points at "item such-and-such on page such-and-such", this route is dangerous. Conversely, if the merged document has to be rewritten anyway, editing in Word and exporting to PDF again may be the easier path.
Keeping the page count and the order — pypdf
If Python is installed, this is the certain route. Installing is one line.
pip install pypdfThe merging code is short too. append tacks a whole file onto the end.
from pypdf import PdfWriter

w = PdfWriter()
for p in [r"C:\path\cover.pdf", r"C:\path\body.pdf", r"C:\path\appendix.pdf"]:
    w.append(p)
with open(r"C:\path\merged.pdf", "wb") as f:
    w.write(f)
The order in the list is the order in the result. We got 10 pages, with the page stamps intact.
A -> B -> C : 10 pages, 196,998 bytes
  A-1, A-2, B-1, B-2, B-3, B-4, B-5, C-1, C-2, C-3
C -> A -> B : 10 pages
  C-1, C-2, C-3, A-1, A-2, B-1, B-2, B-3, B-4, B-5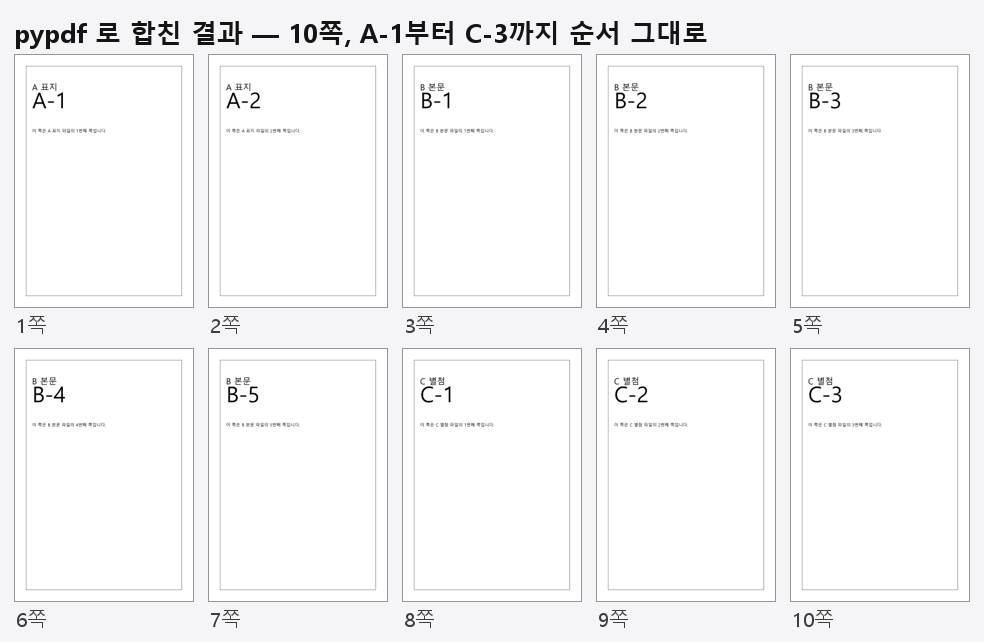
What happens to bookmarks
None of the three files had a single bookmark before the merge, and the result of append had none either. Nothing appears out of nowhere.
If the originals do have bookmarks, it is a different story. We put two on file B — 「B 1장」 (chapter 1, page 1) and 「B 3장」 (chapter 3, page 3) — and appended it after A. In the merged file they pointed at pages 3 and 5. A is 2 pages, so each moved down by two. The page numbers are corrected for you.
Adding a bookmark per file name while you merge makes things easy to find later.
from pypdf import PdfReader, PdfWriter
import os

w, start = PdfWriter(), 0
for p in [r"C:\path\cover.pdf", r"C:\path\body.pdf", r"C:\path\appendix.pdf"]:
    r = PdfReader(p)
    for pg in r.pages:
        w.add_page(pg)
    w.add_outline_item(os.path.splitext(os.path.basename(p))[0], start)
    start += len(r.pages)
with open(r"C:\path\merged.pdf", "wb") as f:
    w.write(f)
merged file 10 pages, 197,715 bytes
bookmarks : Y1_A_표지 -> p.1 / Y1_B_본문 -> p.3 / Y1_C_별첨 -> p.8Because this code moves one page at a time with add_page, bookmarks that were in the originals do not come along. Moving B and its two bookmarks with add_page alone gave a merged file of 10 pages with no bookmarks at all. To keep both, pass a name to append. What came out was the original bookmarks nested one level under the per-file bookmark.
w.append(r"C:\path\Y1_A_표지.pdf", outline_item="표지")
w.append(r"C:\path\Y1_B_본문_책갈피.pdf", outline_item="본문")  # the file carrying 「B 1장」 and 「B 3장」
w.append(r"C:\path\Y1_C_별첨.pdf", outline_item="별첨")
merged file 10 pages, 198,133 bytes
표지 -> p.1
본문 -> p.3
B 1장 -> p.3
B 3장 -> p.5
별첨 -> p.8(The three labels we passed are the Korean words for cover, body and appendix.)
Where merging a whole folder gets the order wrong
Write it as "merge every PDF in this folder in name order" and there is one place it trips.
>>> sorted(["10_열번째.pdf", "2_두번째.pdf", "1_첫번째.pdf"])
['10_열번째.pdf', '1_첫번째.pdf', '2_두번째.pdf']
(The names mean tenth, second and first.) Because the comparison is on characters rather than numbers, 10_ comes before 1_. Rename them with padded digits and everything falls back into place.
>>> sorted(["10_열번째.pdf", "02_두번째.pdf", "01_첫번째.pdf"])
['01_첫번째.pdf', '02_두번째.pdf', '10_열번째.pdf']
Whichever way you merge, counting the pages and checking the first and last page afterwards is the safe habit.
Results
| Method | Needs installing | Pages | Order | Content |
|---|---|---|---|---|
| Select several in Explorer and print | — | — | — | PDFs have no Print command in the first place |
| Open several tabs in Edge, Ctrl+P | nothing | — | — | Only the tab you are viewing prints (total, 2 sheets) |
| One at a time through Microsoft Print to PDF | nothing | — | — | One print, one file. Nowhere to string them together |
| Insert into Word and save as PDF | Word | 10 → 13 | kept | 3 blank pages, title lines gone, borders and type sizes changed |
| pypdf | Python + pypdf | 10 → 10 | kept | Page stamps intact. Bookmarks can be added separately |
What failed
- The first dummy PDF we built came out over 13 MB for 2 pages. We later built the same file both ways and compared. Saved plainly, without
subset_fonts(), it is 13,602,850 bytes (13.0 MB); callsubset_fonts()and save withsave(garbage=4, deflate=True)and it is 63,924 bytes, 0.47% of that. That is what happens when you skip the trim that keeps only the characters actually used from a Korean font. - The first time we opened the printer list in Edge's print pane, the default was set to a different printer, so we had to re-take that screenshot.
- Why the Word merge came to 13 pages, and at which step the three blank pages appeared, we could not establish. All the log holds is that the running page count went 5, 10, 13 as each file went in.
What we did not test
- Whether 「인쇄」 appears in Explorer once the default PDF program is a viewer other than Edge, and whether selecting several files and printing there produces one file.
- The menu that appears when several files are selected in Explorer. What we read was the command list attached to individual files.
- Inserting a PDF through the on-screen menus in Word. We only inserted through automation commands, so we are not quoting menu names.
- Password-protected PDFs, signed PDFs and PDFs with form fields.
- How long merging takes for files over 100 pages, or for scanned, image-based PDFs.
- Whether the bookmarks look the same when the merged file is opened in another PDF viewer. We read the page numbers with Python only.